In plain English. GhettoRak is eight NVIDIA DGX Spark mini computers on a wire shelf. Two network switches tie them together so they can split one big AI model between them. Each Spark has one fast cable to a switch, and one extra-fast cable joins the two switches. It works: all eight talk to each other at full speed. With both switches in and the GPU clocks capped, the whole rack runs on one ordinary 15 A power strip, but only just: our heaviest load, GLM-5.3 on all eight reading a 754K-token prompt, averaged 1,412 W and peaked at 1,457 W (November 13), a little over the 1,440 W such a strip should carry for long. It held. Lighter models stay well under. New October 29: the big GB300 Station is on the same network now, with two 200G links. From the GPU's memory it now uses both at full speed, 392 Gb/s; from ordinary memory both share one narrower PCIe link and stop at about 231.
8
DGX Sparks, one per shelf
2
MikroTik CRS804 switches
200G
one cable per Spark
24 GB/s
all 8, NCCL all_reduce at 256 MiB
392 Gb/s
Station, both ports, GPU memory (new)
1.46 kW
peak at the wall, GLM-5.3 long prompt, both switches
2,200 MHz
GPU clock cap, all eight
Wiring
As built, October 29, 2026, including the new GB300 Station link.
- One cable per Spark. A Spark has two network sockets, but they share about 200G of bandwidth. A second cable does not make 400G, so the second socket stays empty.
- Two devices per cable. In Linux that one cable shows up twice
(
enp1s0f0np0andenP2p1s0f0np0), one per half of the network card. Each gets its own subnet (10.0.0.N,10.0.1.N) and NCCL uses both. - Plain Ethernet. RoCE v2, MTU 9000, no flow control (lossy). Both switches showed zero drops and zero pause frames after the tests below.
- Management is a separate network. Switch 1's spare copper port feeds switch 2, so the management switch needs only one port for both. The fast fabric never touches the house LAN.
| Switch | Cage 1 | Cage 2 | Cage 3 | Cage 4 |
|---|---|---|---|---|
| Switch 2 | Sparks 4, 3 | Sparks 1, 2 | 400G link | Station p0, p1 |
| Switch 1 | Sparks 8, 7 | Sparks 6, 5 | 400G link | empty |
Each Spark cage takes one breakout cable that splits into two 200G ends (2 m on switch 2, 1 m on switch 1). Which Spark sits on which end was read from the switches, not traced by hand.
Shelves
Side view, to scale. Shelf heights are measured from the floor deck.
The frame is a Shelving Inc SC121854-5
(12″ × 18″ × 54″) plus eight extra SI-S1218C
decks, on 5″ threaded casters. It is built sideways so the 18″ side is the depth: a CRS804 is
387 mm deep with its handles, and 391 mm fits between the posts. Two Sparks do not fit side by side, so it is one
per shelf. Build bottom up: bricks and strips, management switch, switch 1, switch 2, then Sparks 8 to 1.
Zip-tie each switch to its deck and hold each Spark down with
6″ mini bungee cords as you go; cables last. CAD source: inference-box-ghettorak.scad.
Nothing printed holds anything down. The only prints are the green labels (inference-box-label-clip.scad + inference-box-label-measured.scad, PLA, on end, 5 mm brim) and these wire-shelf hooks in PETG for cable slack.
Photos
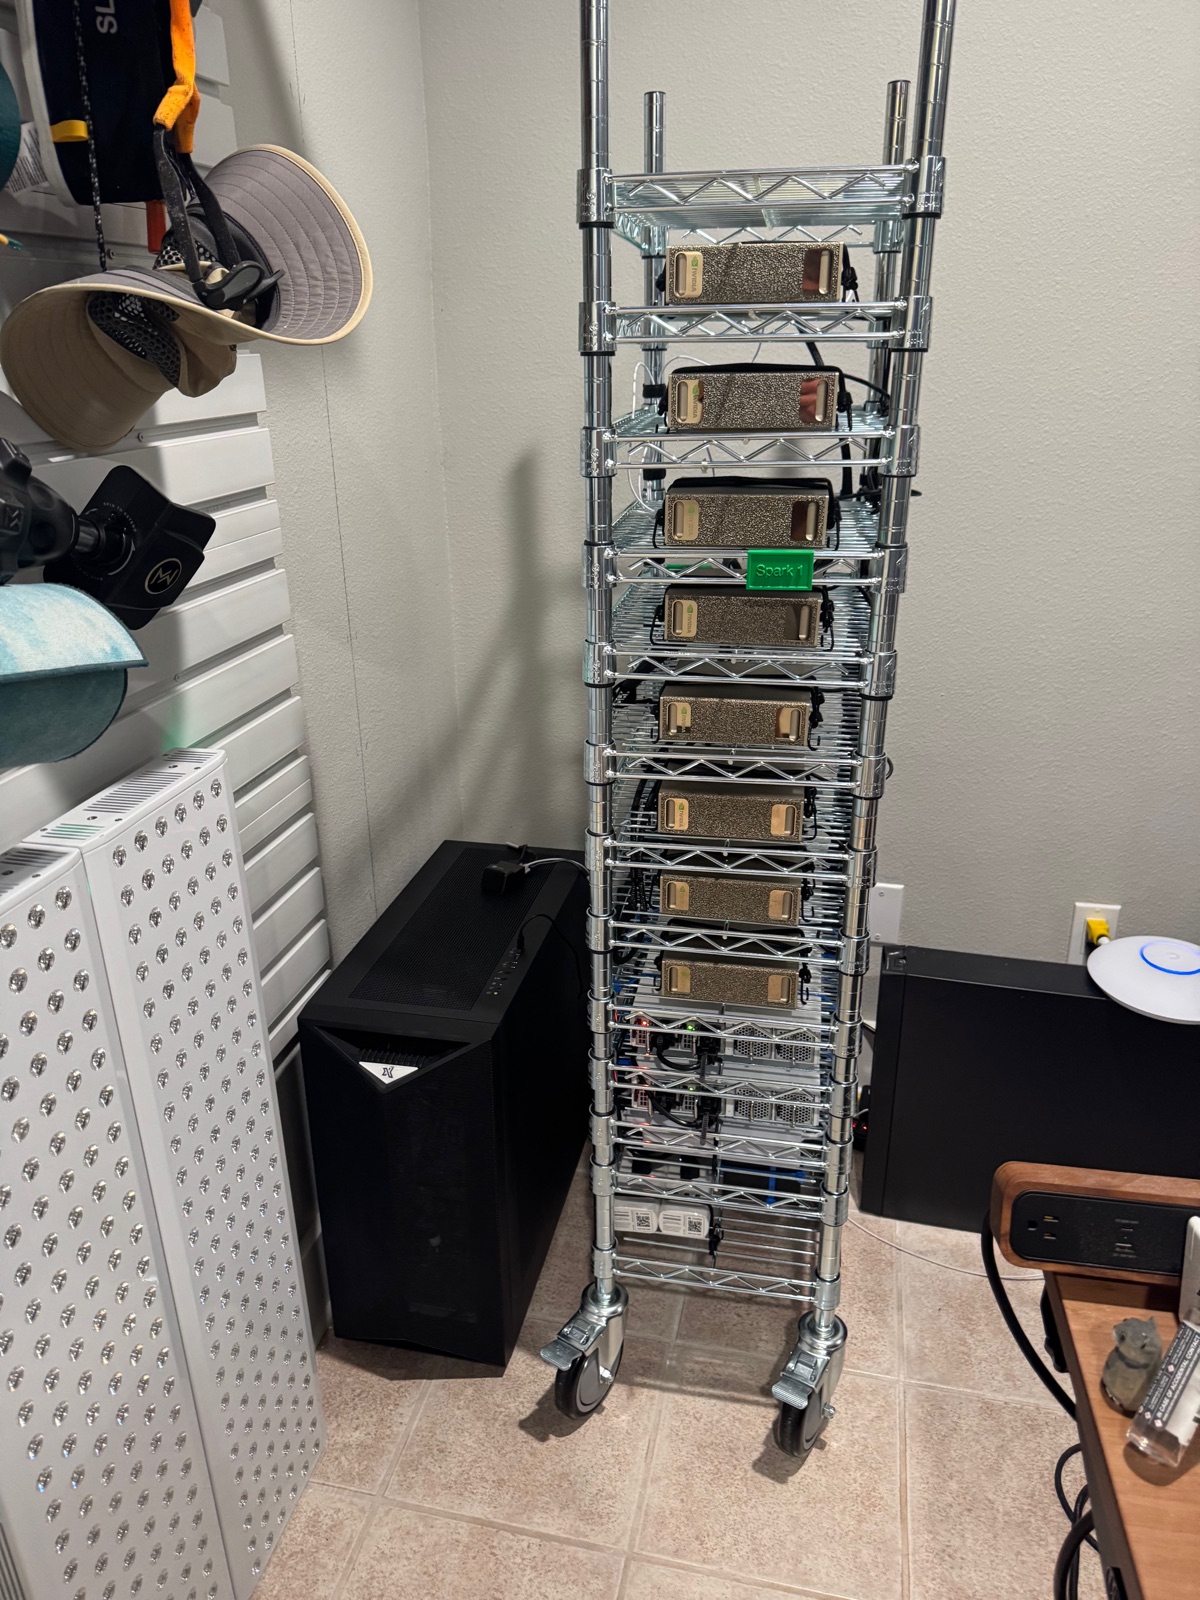
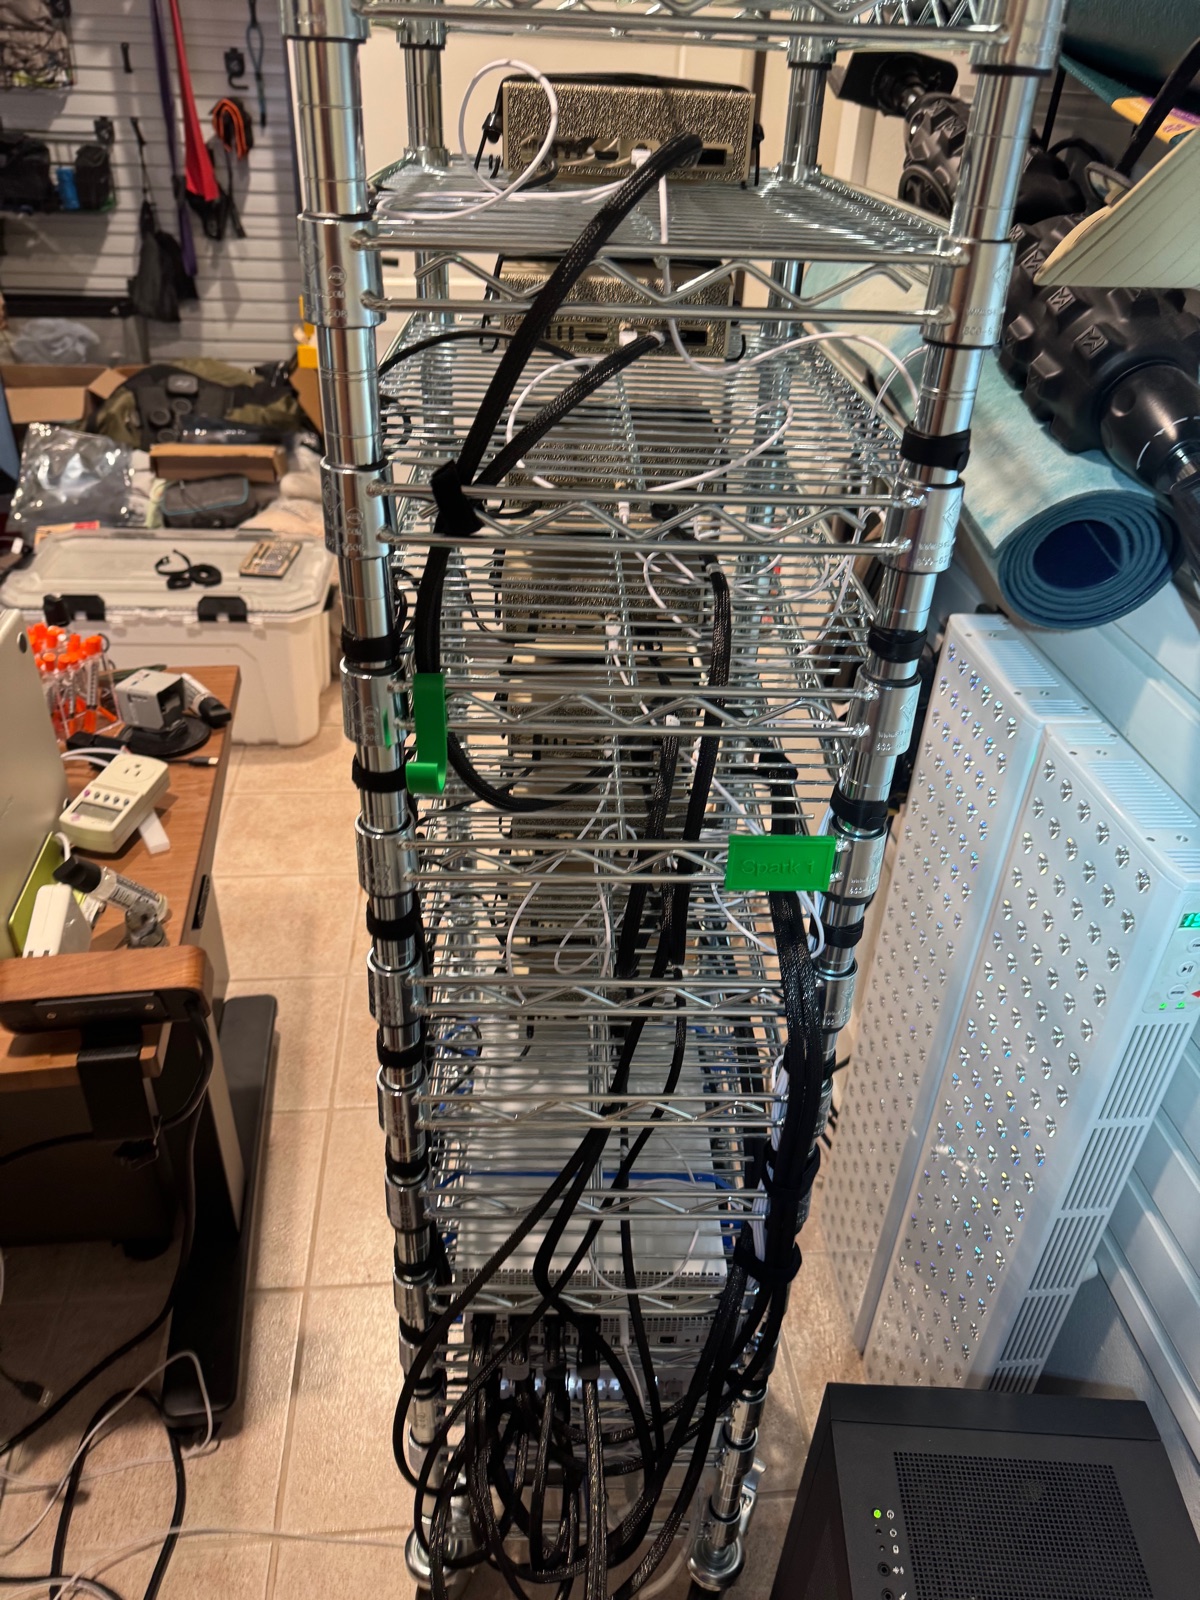
Photos by James, resized for the web, otherwise unaltered.
New: the Station link
Live since October 29. The DGX Station GB300 now sits on the Spark network. One breakout cable in switch 2's fourth cage gives each of its two network ports a 200G link. From the Station, every Spark is one or two switches away.
Measured October 29–30, 2026, with the Station serving its production model. Host memory unless marked GPU.
- Each Station port runs at full speed. One port sending to two Sparks moves 196 Gb/s, which is line rate for 200G. Both ports do it.
- A single Spark is the slower end. One Spark port takes about 98 Gb/s, and a whole Spark (both halves of its card) about 176. That is the same limit the Sparks have with each other.
- From ordinary (host) memory, both Station ports at once stop at about 231 Gb/s out and 211 in, not the ~392 two ports should give. All four test flows got exactly the same share, and bigger messages did not help.
- It is not the switches. We re-ran it on October 30 with the switch counters recorded
before and after:
- Station sending: the same 230.8 Gb/s even with all four Sparks on the Station's own switch, so the 400G link plays no part. The switch dropped nothing on the Station's ports and never told it to slow down. The Station just does not send faster.
- Station receiving: the Station's card sent about 48,000 "pause" frames per port in 8 seconds, asking the switch to stop, and the switch dropped about 10% of the traffic waiting for it. The drops are the result of the Station falling behind, not their cause.
- Found it: one PCIe Gen5 x8 link. The Station's network card has a PCIe switch built in. The card's own ports run at Gen6 x16, but the switch reaches the Grace CPU through a single Gen5 x8 link: about 252 Gb/s raw, about 231 after PCIe overhead. That is exactly where both ports stop. Sending from GPU memory without Data Direct gives the same 230.8, because that traffic crosses the same link.
The Station's network path, read from its PCIe tree on October 30, 2026.
- That link carries more than the network. The two 8 TB drives behind
/models, the 10G house-network port and USB sit behind the same card switch. Loading a model from disk while the fabric is busy splits the same ~231 Gb/s. - The way around it: Data Direct, working since October 30. The card has a second, Gen6 x16
path straight to the GB300 GPU. At first it refused GPU memory (error 524). The cause, as NVIDIA's DGX Station
guide describes, was a PCIe isolation setting that put the card and the GPU in different groups. One boot
setting (
rdma_topo write-grub-acs, then a restart) fixed it. Now GPU-memory transfers skip the x8 link: 392 Gb/s out and 392 in on both ports, against 231 from ordinary memory. - Less loss on the way in. With ECN turned on in the switches (RouterOS 7.25), traffic into the Station loses 85% fewer packets and runs 228 instead of 215 Gb/s from ordinary memory. Spark-to-Spark speed is unchanged.
- The second switch costs about 1 µs. A tiny write takes 2.46 µs to a Spark on the Station's switch and 3.50 µs to one across the 400G link.
- Every path works with jumbo frames: 16 of 16 from the Station to the Sparks, 128 of 128 for the whole network.
Method: ib_write_bw -F -x 3 -q 4 -D 8 --report_gbits (64 KiB messages, one run with
1 MiB) and ib_write_lat (2-byte writes, 20,000 iterations, typical value), RoCE v2.
Station: ConnectX-8 firmware 40.47.1088. GPU-memory runs: perftest 26.07.8 built with CUDA and dma-buf
(--use_cuda_dmabuf, plus --use_data_direct for Data Direct).
Speed
Measured October 29, 2026, with the two-switch layout above. Two runs per line, averaged.
- The new switch is as fast as the old one. Four Sparks on either switch draw the same curve.
- The 400G link between the switches costs nothing we can measure. A test that forces every hop across it lands on top of the one-switch curve.
- Eight Sparks are slower on small messages because the data passes through twice as many hops, and just as fast on big ones (about 24 GB/s).
| Bus bandwidth, GB/s | 1 MiB | 4 MiB | 256 MiB |
|---|---|---|---|
| 4 Sparks, one switch (switch 1 / switch 2) | 10.7 / 11.5 | 20.8 / 20.9 | 23.9 / 23.7 |
| 4 Sparks, every hop across the link (2 runs) | 10.9 / 9.7 | 20.1 / 20.4 | 23.7 / 23.8 |
| All 8 Sparks (2 runs) | 7.4 / 7.2 | 18.6 / 18.6 | 24.0 / 24.0 |
Method: torch.distributed all_reduce, one rank per Spark, fp32, 20 warm-up + 100 timed
iterations, slowest rank counts, bus bandwidth = 2(n−1)/n × bytes ÷ time. NCCL 2.30.7 in
lmsysorg/sglang:v0.5.22-cu130 with NCCL_PROTO=^LL128 and NCCL_MAX_NCHANNELS=8.
This is a network test, not model speed. Why those two NCCL settings matter:
NCCL tuning in plain English.
Power
Whole rack at the wall, summed from the outer strip's outlet meters (10-second samples), both switches in. DeepSeek measured November 12, 2026; GLM-5.3 and idle just after midnight, November 13.
- The strip is the limit, not the wall. Two Tapo P316M strips with per-outlet meters: the outer one plugs into the wall and the inner one (Sparks 1–6) plugs into it, so the outer strip carries the whole rack. 15 A at 120 V is 1,800 W, and 1,440 W for a load that runs for minutes.
- GLM-5.3 on all eight goes just over the line. Same launcher, settings and test prompts as October 16, now with both switches: a 514K-token prompt averaged 1,395 W and peaked at 1,450 W; a 754K-token prompt averaged 1,412 W and peaked at 1,457 W, above 1,440 W for about 100 seconds of its 12 minutes. The strip did not trip, and both prompts found their hidden answer. Each Spark drew 150–168 W on average, the head (Spark 1) the most. On October 16, with one switch, long GLM-5.3 prompts averaged about 1,345 W and peaked at 1,425 W.
- So for long GLM-5.3 runs, move one Spark to a second wall outlet. Spark 8 averaged 155 W on the 754K prompt; moving it would leave the strip about 1,300 W at peak.
- DeepSeek-V4.1-Flash fits easily. Both four-Spark lanes ran at once, each fed two cold ~212K-token prompts at a time for five minutes (18 of 18 finished): 1,245 W average, 1,324 W peak, 116 W under the line. Sixteen users decoding on each lane: 1,235 W average, 1,271 W peak.
- The two switches draw 105 W. Switch 1 takes 50 W at the wall and switch 2 55 W (their own power supplies read 42 and 46 W); the UniFi management switch takes 49 W.
- Idle: 504 W for the whole rack with no model loaded, 43–44 W per Spark (448 W on October 16, before switch 2). With a model loaded and waiting: 574–577 W.
- Cap the GPU clocks. At stock clocks a long prompt drew about 200 W per Spark and tripped
the strip (1,717 W average, October 16). Every Spark now runs
nvidia-smi -lgc 0,2200at boot (a small systemd unit). That cut wall power 22% with no loss in decode speed. Undo:sudo systemctl disable --now gb10-clocklock && sudo nvidia-smi -rgc. GB10 has no power-limit setting, so the clock is the only lever. - After a trip, some Sparks stay off until you press their power buttons. Nothing starts by itself: containers have no restart policy, so check the links before relaunching anything.
Method: GLM-5.3 NVFP4 on vLLM, tensor-parallel over all eight, with the October 16 settings (4-bit KV cache, 1M context, MTP depth 3) and the same two needle-in-a-haystack prompts (513,814 and 754,233 tokens, both passed). DeepSeek: both live DeepSeek-V4.1-Flash TP4 lanes (Sparks 1–4 on SGLang, Sparks 5–8 on vLLM), fed cold prompts of random words (~212K tokens, 16-token answers) so no cache helps. Load driven from another machine. Tapo P316M outlet meters read through Home Assistant into Prometheus, 10-second samples, first 20 seconds of each phase dropped.
Copy it
Step-by-step guide with checks: Networking DGX Station and DGX Sparks with MikroTik CRS804.
Each switch (RouterOS 7.25). Keep the factory bridge for management only and turn its hardware offload off, so the fabric bridge gets the switch chip:
/interface/bridge/port/set [find bridge=bridge] hw=no
/interface/bridge/add name=fabric protocol-mode=rstp igmp-snooping=no
:foreach p in={"qsfp56-dd-1-1";"qsfp56-dd-1-5";"qsfp56-dd-2-1";"qsfp56-dd-2-5"} do={
  /interface/ethernet/set [find name=$p] auto-negotiation=no \
    speed=200G-baseCR4 fec-mode=fec91 l2mtu=9216 mtu=9000
  /interface/bridge/port/add bridge=fabric interface=$p hw=yes
}
# cage 3: the 400G link to the other switch
/interface/ethernet/set [find name=qsfp56-dd-3-1] auto-negotiation=no \
    speed=400G-baseCR8 fec-mode=fec91 l2mtu=9216 mtu=9000
/interface/bridge/port/add bridge=fabric interface=qsfp56-dd-3-1 hw=yes
# ECN marking on the default traffic class (cuts RoCE loss into a busy receiver)
/interface/ethernet/switch/qos/tx-manager/queue/set [find traffic-class=1] ecn=yes
Each Spark (N = Spark number). Delete the two auto-created "Wired connection" profiles first, then one netplan file, no gateway:
network:
  version: 2
  renderer: NetworkManager
  ethernets:
    enp1s0f0np0:
      addresses: [10.0.0.N/24]
      mtu: 9000
      dhcp4: no
      dhcp6: no
      accept-ra: no
      link-local: []
    enP2p1s0f0np0:
      addresses: [10.0.1.N/24]
      mtu: 9000
      dhcp4: no
      dhcp6: no
      accept-ra: no
      link-local: []
GB300 Station. Its ConnectX-8 will not link with the switch's forced 200G while it is
auto-negotiating, so force it. Same addresses and ARP rules as the Sparks, with .9 as the host number:
sudo ethtool -s enP1p3s0f0np0 autoneg off speed 200000 duplex full lanes 4
sudo ethtool --set-fec enP1p3s0f0np0 encoding rs
sudo ip link set enP1p3s0f0np0 mtu 9000
sudo ip addr add 10.0.0.9/24 dev enP1p3s0f0np0
# same for enP1p3s0f1np1 with 10.0.1.9/24
sudo sysctl -w net.ipv4.conf.enP1p3s0f0np0.arp_ignore=1 net.ipv4.conf.enP1p3s0f0np0.arp_announce=2
On the switch, the two Station legs are set up exactly like the Spark legs (cage 4, lanes 1 and 5).
Save them with netplan (addresses, MTU) and a small boot service (the ethtool and sysctl lines). For GPU-memory
transfers at full speed, also run sudo rdma_topo check; if it reports wrong ACS values, run
sudo rdma_topo write-grub-acs, sudo update-grub and restart.
NCCL:
NCCL_IB_HCA=rocep1s0f0,roceP2p1s0f0
NCCL_SOCKET_IFNAME=enp1s0f0np0
NCCL_IB_ROCE_VERSION_NUM=2
NCCL_IB_GID_INDEX=3
NCCL_PROTO=^LL128
NCCL_MAX_NCHANNELS=8
Pin NCCL_SOCKET_IFNAME, or NCCL may start up over Docker or Tailscale. Check it worked: both links
up at 200G with MTU 9000 on every Spark, then ping -M do -s 8972 between every pair on both subnets
(112 of 112 for eight Sparks).
Software
| Item | Now (Sparks checked November 3; switches and Station October 29) |
|---|---|
| OS | Ubuntu 24.04 (DGX OS), kernel 7.0.0-1024-nvidia, headless |
| GPU driver | 580.178.04, NVIDIA's stock driver; nothing held. Dashboard updates are off, and we test each update on four Sparks first. |
| Spark firmware | October 2026 release; display memory set to 0.5 GB |
| ConnectX-7 firmware | 28.45.4028 |
| GPU clocks | capped at 2,200 MHz at boot |
| Switches | RouterOS 7.25 on both (RouterBOARD firmware 7.24.2), ECN on |
| GB300 Station NIC | ConnectX-8, firmware 40.47.1088; card ports Gen6 x16, link to the CPU Gen5 x8 |
Kernel 7.0 is fine now. On November 2 and 3 we tested 7.0.0-1019 and 7.0.0-1024 on four of these Sparks, then moved all eight to 7.0.0-1024 on the stock 580.178.04 driver. 7.0.0-1019 does break multi-node RDMA unless you boot with kho=off; 7.0.0-1024 does not need it. Results and our full setup: Testing DGX Spark Kernels.
Buy
| Qty | What | Part |
|---|---|---|
| 1 | 12″ × 18″ × 54″ chrome wire rack, 5 shelves (build it sideways) | SC121854-5 |
| 8 | Extra 12 × 18 shelves with clips (13 decks total) | SI-S1218C |
| 1 | 5″ threaded casters, 4-pack (threaded, not stem) | SI-APC5WB-4 |
| 2 | MikroTik CRS804 switch | CRS804-4DDQ-hRM |
| 4 | 400G → 2 × 200G breakout cable, MikroTik-coded, one per pair of Sparks: two 2 m, two 1 m | NADDOD Q2Q56-400G-CU2 / -CU1 |
| 1 | 400G cable, 1 m, switch to switch | NADDOD QDD-400G-CU1 |
| 1 | 400G → 2 × 200G breakout for the GB300 Station, 1 m (ours is Mellanox-coded) | NADDOD Q2Q56-400G-CU1 |
| 2 | 15 A smart strip with per-outlet power meters | Tapo P316M |
| 1 | 10G management switch, fanless | USW-Pro-XG-8-PoE |
| 9 | Cat6a patch cords (8 Sparks + switch 1 → switch 2) | — |
| 12 | 1 ft power cords for the Spark bricks | C5 → 5-15P |
| 1 | 6″ mini bungee cords with plastic-coated hooks, 15-pack (hold the Sparks) | Joneaz B09CM1JN5S |
| 1 | Long blue nylon zip ties (hold the switches) | — |
Skip: taller posts (54″ is enough), 0.5 m breakouts (could not make one work here), InfiniBand OSFP splitters and QSFP112 cables (wrong socket for the CRS804), 400G optics for the Station until 2 × 200G proves too slow, extra fans, and a UPS inside the frame.
Next
- Use Data Direct from real software (NCCL 2.27.3+, UCX 1.20+) for Station-to-Spark model and cache transfers.
- Give one Spark its own wall outlet before long GLM-5.3 runs: on one strip it peaks at 1,457 W.